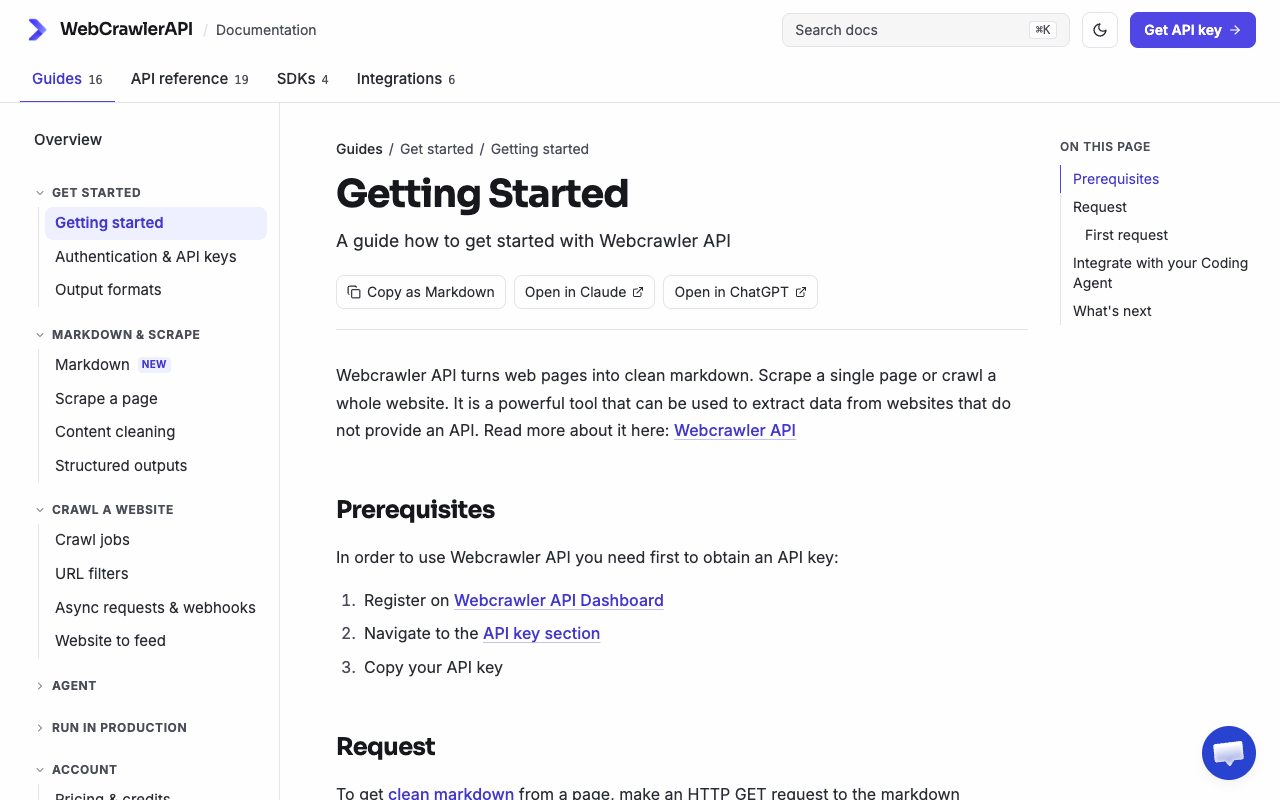
WebCrawlerAPI website screenshot

WebCrawlerAPI

WebCrawlerAPI is a web crawling and scraping API from 103 Labs (Netherlands) that turns websites into clean, LLM-ready markdown, cleaned text, HTML or link lists for AI agents, support bots and RAG pipelines. It offers asynchronous multi-page crawl jobs (POST /v1/crawl with polling or webhooks), single-page scraping (POST /v2/scrape, sync or async, with prompt-based structured outputs validated against a JSON Schema), scheduled change-detection Feeds delivered as Atom 1.0, JSON Feed 1.1 or webhooks, a prompt-driven autonomous crawling agent with a required per-run spend cap, and organization usage/balance endpoints. Requests authenticate with a Bearer API key; usage is metered per successfully crawled page on a $0/month pay-as-you-go tier or $29/$99/$499 monthly plans, with 7-day caching (cache hits free). Published surfaces: a Swagger 2.0 document behind a live Swagger UI, an Agent API OpenAPI 3.0.3, an A2A agent card and RFC 9727 API catalog at /.well-known/, llms.txt, SDKs for JavaScript, Python, PHP, .NET and Java, an npm MCP server (local stdio), the webcr CLI, a Claude Code Agent Skill, a public Postman collection and a dated changelog.

WebCrawlerAPI publishes 8 API contracts indexed on the APIs.io network, including Agent API, Feeds API, Jobs API, and 5 more. Tagged areas include Web Scraping, Web Crawling, Data Extraction, Markdown, and AI Agents.

The WebCrawlerAPI catalog on APIs.io includes 1 event-driven AsyncAPI specification and 1 Spectral governance ruleset.

WebCrawlerAPI’s developer surface includes documentation, API reference, getting-started guide, support, engineering blog, changelog, pricing, and 43 more developer resources.

65.8/100 strong ▲ 10.0 Agent 43/100 agent ready Front door AI 5/6 prominent Heartbeat 100/100 alive saas Full breakdown ↓
scored 2026-11-13 · rubric v0.28.0 · Show this score on your site →
AccessFreemiumSelf serve⚡ Free to try
3 published contracts 2 MCP Servers 3 Agent Skills
Web ScrapingWeb CrawlingData ExtractionMarkdownAI AgentsLLMRAGWeb FeedsChange DetectionStructured DataMCPA2AAgent-Native

Kin Score

Kin Score Kin Score How this is scored →
scored 2026-11-13 · rubric v0.28.0
Regulatory Posture applies to this provider. Its tags matched the Horizontal (data, software, accessibility, platform) regime, so Regulatory Posture carries 15 points of the composite. If this regime is wrong for your business, say so on your provider repo — the applicability map is public and we will correct it.
Create-or-Update Ergonomics applies to this provider. This API accepts writes, so it carries 10 points of the composite. It is scored from the published contracts themselves: whether a caller can create-or-update in one call, whether the write accepts a key the caller already holds, and whether the response says which branch ran. Without that, every write needs a search-and-branch in front of it, and the first time that check is skipped a duplicate record is created. Scored against the observed mean rather than raw — a provider at the catalog average is unchanged by this facet, not penalised by it.
The six quality facets above are damped to 75 points between them, because the conditional facet above carries the other 25. That is why each facet's contribution is shown against a damped maximum: raising a quality facet moves the composite by 75% of its nominal weight, not 100%. The full arithmetic is at apis.io/rating/.
Show this score on your site. Kin Score badge preview for WebCrawlerAPI It updates itself when the score changes. Paste this where you link to your API docs:
<a href="https://apis.io/providers/webcrawlerapi-com/"><img src="https://apis.io/badge/webcrawlerapi-com/card.svg" alt="WebCrawlerAPI on APIs.io — Kin Score by API Evangelist"></a>
Other styles, a README pill and a shields.io endpoint are on the badge page.
Raise your score.
Agent readiness — checks not met, largest first (exact, from this profile):
4 more unmet checks in the Agent Readiness table above.
Kin Score — facets with the most composite points still available (weight × headroom):
Each check links to what satisfies it. Publish the artifact, or tell us where it already lives, and the score moves on the next scoring run.
Not sure how this applies to your stack? Ask about any one item. Kin Lane reads every question, looks at your profile and your situation, and replies with what a fix would take — scoped to that one area, priced up front, yours whether you ship it or not. Ask a question →
Ask about:
Webcrawlerapi Com · a person reads this and replies by email.
or email info@apis.io
Improve this rating by publishing the missing artifacts — every area above can be raised, and the full rubric is at apis.io/rating/. Every facet and dimension name above is a link: it opens that measurement's own page — what it means, the exact checks that feed it, how the whole catalog distributes on it, and the providers at the top of it. This rating is computed from the provider profile at artifacts.apis.io/webcrawlerapi-com/apis.yml: open an issue on github.com/api-evangelist/webcrawlerapi-com to ask a question or point us at an artifact you publish. Submit an artifact on GitHub — free → Manage your own listing — the Influence plan, $499/mo →

Markets this provider is in provisional

The Kin Score Market layer reads a provider inside its market: its position, and how deep its integrations go. Depth is only comparable within a position. Provisional and unweighted: not part of the Kin Score or agent readiness.

MarketPositionDepthRegistered MCP serverDeclares compatibility
AI Agents (A2A agent cards) distribution 21.7 - 2
Agent Skills (SKILL.md packages) distribution 21.7 - 2
Official SDKs on Packagist, pub.dev and Hex distribution 21.7 - 2

Registered MCP server and declares compatibility are report only — not weighted. Undeclared means we found nothing we can read, so there is no number: we never infer integrations.

Standards implemented 5

Standards this provider implements or carries. De facto ones are profiled and measured by the API Commons; formal ones come from the standards directory and are linked by the provider's own tags. The evidence column says how each claim was established — not that it was made.

tagged — the provider's own APIs.json carries the standard as a tag; implementation not verified
measured — observed by APIs.io (documented)
measured — observed by APIs.io (published)

APIs 8

Individual APIs this provider publishes, each with its own machine-readable definition.

WebCrawlerAPI MCP Server

Official Model Context Protocol server distributed as the npm package webcrawler-mcp (npx -y webcrawler-mcp) and run locally over stdio - or self-hosted over streamable HTTP wit...

WebCrawlerAPI Agent Card

A2A-style agent card served from https://webcrawlerapi.com/.well-known/agent-card.json describing "WebCrawlerAPI Agent" (version 1.0.0) with three skills - scrape, crawl and cra...

WebCrawlerAPI Agent API

The Agent API from WebCrawlerAPI — 3 operation(s) for agent.

WebCrawlerAPI Feeds API

The Feeds API from WebCrawlerAPI — 9 operation(s) for feeds.

WebCrawlerAPI Jobs API

The Jobs API from WebCrawlerAPI — 6 operation(s) for jobs.

WebCrawlerAPI Organization API

The Organization API from WebCrawlerAPI — 1 operation(s) for organization.

WebCrawlerAPI Status API

The Status API from WebCrawlerAPI — 2 operation(s) for status.

WebCrawlerAPI V2 Scraping API

The V2 Scraping API from WebCrawlerAPI — 2 operation(s) for v2 scraping.

Scroll for all 8

MCP Servers 2

Model Context Protocol servers that expose these APIs to AI agents.

WebCrawlerAPI MCP Server

WebCrawlerAPI ships an official MCP server as an npm package (webcrawler-mcp) that a user runs locally over stdio, or self-hosts over HTTP with USE_HTTP=true. There is NO provid...

MCP SERVER

Agent Skills 3

Packaged agent skills for driving this provider's APIs from an AI assistant.

webcrawlerapi

AGENT SKILL

WebCrawlerAPI pricing

Prices published by WebCrawlerAPI, read 2026-10-28 from webcrawlerapi.com/docs/pricing.

PlanPrice
Pay as you go $0/month
Professional $99/month
Business $499/month

Plan details, limits and sources →

Billed by: page · FinOps profile →

Pricing Plans 2

Published pricing tiers and plan structures.

Rate Limits 1

Documented rate limits and quota policies.

WebCrawlerAPI Rate Limits

0 limits

RATE LIMITS

Terms of Service 1

What its API terms permit and prohibit, quoted from its own page.

WebCrawlerAPI

8 quoted statements, read from WebCrawlerAPI's own page on 2026-11-10.

TERMS

Privacy & Data 1

Its role, the data it processes, retention and transfers, quoted from its own privacy page.

WebCrawlerAPI

11 quoted statements, read from WebCrawlerAPI's own page on 2026-11-10.

PRIVACY

Eligibility 1

Who may sign up and where, quoted from its own terms.

WebCrawlerAPI

4 quoted statements, read from WebCrawlerAPI's own page on 2026-11-10.

ELIGIBILITY

Data License 1

How its data and outputs may be reused, quoted from its own terms.

WebCrawlerAPI

2 quoted statements, read from WebCrawlerAPI's own page on 2026-11-10.

LICENSE

FinOps 1

Cost, billing, and metering signals for API financial operations.

Event Specifications 1

AsyncAPI definitions for this provider's event-driven and streaming APIs.

Spectral Rules 1

Spectral governance rulesets for linting and validating these APIs. Counts are the severity each rule declares, not results of running them.

WebCrawlerAPI API Rules

71 rules · 63 error-severity 5 warn-severity 3 info-severity

SPECTRAL

OpenAPI Overlays 1

Overlays applied on top of this provider's contracts. Each card says who wrote it: a document the provider publishes, or one API Evangelist derived or generated.

WebCrawlerAPI Openapi Overlay

28 actions · documentation · webcrawlerapi-com-openapi.yml

DERIVED

Security Posture 2

Authentication, domain security, vulnerability disclosure, and trust-center signals.

WebCrawlerAPI Authentication

apiKey · 1 scheme

SECURITY

WebCrawlerAPI Domain Security

TLSv1.3 · DMARC

SECURITY

Resources

Get Started 4

Portal, sign-up, and the first successful call

Documentation 2

Reference material describing how the API behaves

Agent Surfaces 6

MCP servers, agent skills, and machine-readable catalogs

Design & Contract 6

Pagination, idempotency, versioning, errors, and events

Build 6

SDKs, sample code, and the tooling you integrate with

Access & Security 2

Authentication, authorization, and security posture

Operate 5

Status, limits, changes, and where to get help

Commercial 6

Pricing, plans, and the legal terms of use

Company 4

The organization behind the API

Other 9

Properties that don't map to a standard resource type

Scroll for all 9

Source (apis.yml)

apis.yml Raw ↑
aid: webcrawlerapi-com
name: WebCrawlerAPI
description: 'WebCrawlerAPI is a web crawling and scraping API from 103 Labs (Netherlands) that turns websites into clean,
  LLM-ready markdown, cleaned text, HTML or link lists for AI agents, support bots and RAG pipelines. It offers asynchronous
  multi-page crawl jobs (POST /v1/crawl with polling or webhooks), single-page scraping (POST /v2/scrape, sync or async, with
  prompt-based structured outputs validated against a JSON Schema), scheduled change-detection Feeds delivered as Atom 1.0,
  JSON Feed 1.1 or webhooks, a prompt-driven autonomous crawling agent with a required per-run spend cap, and organization
  usage/balance endpoints. Requests authenticate with a Bearer API key; usage is metered per successfully crawled page on
  a $0/month pay-as-you-go tier or $29/$99/$499 monthly plans, with 7-day caching (cache hits free). Published surfaces: a
  Swagger 2.0 document behind a live Swagger UI, an Agent API OpenAPI 3.0.3, an A2A agent card and RFC 9727 API catalog at
  /.well-known/, llms.txt, SDKs for JavaScript, Python, PHP, .NET and Java, an npm MCP server (local stdio), the webcr CLI,
  a Claude Code Agent Skill, a public Postman collection and a dated changelog.'
deliveryModel:
  model: saas
  license_evidence:
    not_product:
    - webcrawlerapi/webcrawlerapi-mcp
  open_source: unknown
  commercial: true
  callable_host: true
  label: Hosted service · you call their endpoint
  confidence: low
  source:
  - openapi
  - pricing
  - repository-not-product
  generated: '2026-09-25'
  method: derived
accessModel:
  pricing: freemium
  onboarding: self-serve
  trial: false
  try_now: true
  public: false
  gated: none
  gated_source:
  - onboarding
  label: Freemium · Self-serve signup
  confidence: high
  source:
  - plans
  - authentication
  - rate-limits
  - security
  generated: '2026-11-13'
  method: derived
image: https://webcrawlerapi.com/favicon.png
url: https://raw.githubusercontent.com/api-evangelist/webcrawlerapi-com/refs/heads/main/apis.yml
x-type: company
x-source: harvest:a2a-registry
x-tier: profiled
x-tier-reason: enrichment pass 2026-09-19 (local-v3; was a2a-registry harvest stub)
specificationVersion: '0.20'
created: '2026-09-19'
modified: '2026-09-19'
tags:
- Web Scraping
- Web Crawling
- Data Extraction
- Markdown
- AI Agents
- LLM
- RAG
- Web Feeds
- Change Detection
- Structured Data
- MCP
- A2A
- Agent-Native
tags_raw:
- Web Scraping
- Web Crawling
- Data Extraction
- Markdown
- AI Agents
- LLM
- RAG
- Web Feeds
- Change Detection
- Structured Data
- MCP
- A2A
- agent-native
apis:
- aid: webcrawlerapi-com:webcrawlerapi-mcp-server
  name: WebCrawlerAPI MCP Server
  description: 'Official Model Context Protocol server distributed as the npm package webcrawler-mcp (npx -y webcrawler-mcp)
    and run locally over stdio - or self-hosted over streamable HTTP with USE_HTTP=true - by the user; there is no provider-hosted
    remote endpoint. It exposes one tool, webcrawler-scrape (url, optional prompt, optional main_content_only), which POSTs
    to https://api.webcrawlerapi.com/v2/scrape with the API key from the WEBCRAWLER_API_KEY environment variable and returns
    markdown (or structured_data when a prompt is set). Source: github.com/WebCrawlerAPI/webcrawlerapi-mcp.'
  humanURL: https://webcrawlerapi.com/docs/sdk/mcp
  baseURL: https://api.webcrawlerapi.com
  tags:
  - MCP
  - AI Agents
  - Web Scraping
  - Agent-Native
  tags_raw:
  - MCP
  - AI Agents
  - Web Scraping
  - agent-native
  properties:
  - type: MCPServer
    url: mcp/webcrawlerapi-com-mcp.yml
  - type: MCPServer
    name: webcrawler-mcp on npm (local stdio package)
    url: https://www.npmjs.com/package/webcrawler-mcp
  - type: ToolCrosswalk
    url: mcp/webcrawlerapi-com-tool-crosswalk.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/sdk/mcp
  - type: SourceCode
    url: https://github.com/WebCrawlerAPI/webcrawlerapi-mcp
  image: https://webcrawlerapi.com/favicon.png
- aid: webcrawlerapi-com:webcrawlerapi-a2a-agent-card
  name: WebCrawlerAPI Agent Card
  description: 'A2A-style agent card served from https://webcrawlerapi.com/.well-known/agent-card.json describing "WebCrawlerAPI
    Agent" (version 1.0.0) with three skills - scrape, crawl and crawling-agent - Bearer securitySchemes, text/markdown/JSON
    input and output modes, a healthCheckUrl and an openapi_url pointing at the Agent API OpenAPI. Graded FLAVORED against
    A2A 1.0.0: protocolVersion is absent and the card''s url is the REST base path https://api.webcrawlerapi.com/v1, which
    does not answer A2A JSON-RPC (a tasks/get POST returns 404). It is a real, provider-served discovery document for the
    REST API rather than a working A2A endpoint.'
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com/v1
  tags:
  - A2A
  - AI Agents
  - Agent-Native
  tags_raw:
  - A2A
  - AI Agents
  - agent-native
  properties:
  - type: AgentCard
    url: a2a/webcrawlerapi-com-a2a.yml
  - type: AgentCard
    name: A2A Agent Card (provider-hosted)
    url: https://webcrawlerapi.com/.well-known/agent-card.json
  image: https://webcrawlerapi.com/favicon.png
- aid: webcrawlerapi-com:webcrawlerapi-com-agent-api
  name: WebCrawlerAPI Agent API
  description: The Agent API from WebCrawlerAPI — 3 operation(s) for agent.
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com
  tags:
  - Agents
  tags_raw:
  - Agent
  properties:
  - type: OpenAPI
    url: openapi/webcrawlerapi-com-agent-api-openapi.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/getting-started
  - type: APIReference
    url: https://api.webcrawlerapi.com/swagger/index.html
  - type: APIReference
    url: https://webcrawlerapi.com/docs/api/crawl
  - type: Authentication
    url: authentication/webcrawlerapi-com-authentication.yml
  - type: Conventions
    url: conventions/webcrawlerapi-com-conventions.yml
  - type: ErrorCatalog
    url: errors/webcrawlerapi-com-problem-types.yml
  - type: DataModel
    url: data-model/webcrawlerapi-com-data-model.yml
  - type: Webhooks
    url: asyncapi/webcrawlerapi-com-webhooks.yml
  - type: RateLimits
    url: rate-limits/webcrawlerapi-com-rate-limits.yml
  - type: Postman
    url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
- aid: webcrawlerapi-com:webcrawlerapi-com-feeds-api
  name: WebCrawlerAPI Feeds API
  description: The Feeds API from WebCrawlerAPI — 9 operation(s) for feeds.
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com
  tags:
  - Feed
  tags_raw:
  - Feeds
  properties:
  - type: OpenAPI
    url: openapi/webcrawlerapi-com-feeds-api-openapi.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/getting-started
  - type: APIReference
    url: https://api.webcrawlerapi.com/swagger/index.html
  - type: APIReference
    url: https://webcrawlerapi.com/docs/api/crawl
  - type: Authentication
    url: authentication/webcrawlerapi-com-authentication.yml
  - type: Conventions
    url: conventions/webcrawlerapi-com-conventions.yml
  - type: ErrorCatalog
    url: errors/webcrawlerapi-com-problem-types.yml
  - type: DataModel
    url: data-model/webcrawlerapi-com-data-model.yml
  - type: Webhooks
    url: asyncapi/webcrawlerapi-com-webhooks.yml
  - type: RateLimits
    url: rate-limits/webcrawlerapi-com-rate-limits.yml
  - type: Postman
    url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
- aid: webcrawlerapi-com:webcrawlerapi-com-jobs-api
  name: WebCrawlerAPI Jobs API
  description: The Jobs API from WebCrawlerAPI — 6 operation(s) for jobs.
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com
  tags:
  - Job
  tags_raw:
  - Jobs
  properties:
  - type: OpenAPI
    url: openapi/webcrawlerapi-com-jobs-api-openapi.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/getting-started
  - type: APIReference
    url: https://api.webcrawlerapi.com/swagger/index.html
  - type: APIReference
    url: https://webcrawlerapi.com/docs/api/crawl
  - type: Authentication
    url: authentication/webcrawlerapi-com-authentication.yml
  - type: Conventions
    url: conventions/webcrawlerapi-com-conventions.yml
  - type: ErrorCatalog
    url: errors/webcrawlerapi-com-problem-types.yml
  - type: DataModel
    url: data-model/webcrawlerapi-com-data-model.yml
  - type: Webhooks
    url: asyncapi/webcrawlerapi-com-webhooks.yml
  - type: RateLimits
    url: rate-limits/webcrawlerapi-com-rate-limits.yml
  - type: Postman
    url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
- aid: webcrawlerapi-com:webcrawlerapi-com-organization-api
  name: WebCrawlerAPI Organization API
  description: The Organization API from WebCrawlerAPI — 1 operation(s) for organization.
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com
  tags:
  - Organization
  properties:
  - type: OpenAPI
    url: openapi/webcrawlerapi-com-organization-api-openapi.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/getting-started
  - type: APIReference
    url: https://api.webcrawlerapi.com/swagger/index.html
  - type: APIReference
    url: https://webcrawlerapi.com/docs/api/crawl
  - type: Authentication
    url: authentication/webcrawlerapi-com-authentication.yml
  - type: Conventions
    url: conventions/webcrawlerapi-com-conventions.yml
  - type: ErrorCatalog
    url: errors/webcrawlerapi-com-problem-types.yml
  - type: DataModel
    url: data-model/webcrawlerapi-com-data-model.yml
  - type: Webhooks
    url: asyncapi/webcrawlerapi-com-webhooks.yml
  - type: RateLimits
    url: rate-limits/webcrawlerapi-com-rate-limits.yml
  - type: Postman
    url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
- aid: webcrawlerapi-com:webcrawlerapi-com-status-api
  name: WebCrawlerAPI Status API
  description: The Status API from WebCrawlerAPI — 2 operation(s) for status.
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com
  tags:
  - Status
  properties:
  - type: OpenAPI
    url: openapi/webcrawlerapi-com-status-api-openapi.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/getting-started
  - type: APIReference
    url: https://api.webcrawlerapi.com/swagger/index.html
  - type: APIReference
    url: https://webcrawlerapi.com/docs/api/crawl
  - type: Authentication
    url: authentication/webcrawlerapi-com-authentication.yml
  - type: Conventions
    url: conventions/webcrawlerapi-com-conventions.yml
  - type: ErrorCatalog
    url: errors/webcrawlerapi-com-problem-types.yml
  - type: DataModel
    url: data-model/webcrawlerapi-com-data-model.yml
  - type: Webhooks
    url: asyncapi/webcrawlerapi-com-webhooks.yml
  - type: RateLimits
    url: rate-limits/webcrawlerapi-com-rate-limits.yml
  - type: Postman
    url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
- aid: webcrawlerapi-com:webcrawlerapi-com-v2-scraping-api
  name: WebCrawlerAPI V2 Scraping API
  description: The V2 Scraping API from WebCrawlerAPI — 2 operation(s) for v2 scraping.
  humanURL: https://webcrawlerapi.com/docs/getting-started
  baseURL: https://api.webcrawlerapi.com
  tags:
  - V2 Scraping
  properties:
  - type: OpenAPI
    url: openapi/webcrawlerapi-com-v2-scraping-api-openapi.yml
  - type: Documentation
    url: https://webcrawlerapi.com/docs/getting-started
  - type: APIReference
    url: https://api.webcrawlerapi.com/swagger/index.html
  - type: APIReference
    url: https://webcrawlerapi.com/docs/api/crawl
  - type: Authentication
    url: authentication/webcrawlerapi-com-authentication.yml
  - type: Conventions
    url: conventions/webcrawlerapi-com-conventions.yml
  - type: ErrorCatalog
    url: errors/webcrawlerapi-com-problem-types.yml
  - type: DataModel
    url: data-model/webcrawlerapi-com-data-model.yml
  - type: Webhooks
    url: asyncapi/webcrawlerapi-com-webhooks.yml
  - type: RateLimits
    url: rate-limits/webcrawlerapi-com-rate-limits.yml
  - type: Postman
    url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
maintainers:
- FN: Kin Lane
  email: kin@apievangelist.com
- FN: APIs.json
  email: info@apis.io
common:
- type: Website
  url: https://webcrawlerapi.com/
- type: DeveloperPortal
  url: https://webcrawlerapi.com/docs/getting-started
- type: Documentation
  url: https://webcrawlerapi.com/docs/getting-started
- type: APIReference
  url: https://api.webcrawlerapi.com/swagger/index.html
- type: GettingStarted
  url: https://webcrawlerapi.com/docs/getting-started
- type: Support
  url: mailto:support@webcrawlerapi.com
- type: Blog
  url: https://webcrawlerapi.com/blog
- type: BlogRSS
  url: https://webcrawlerapi.com/rss.xml
- type: ChangeLog
  url: https://webcrawlerapi.com/changelog
- type: ChangeLog
  url: changelog/webcrawlerapi-com-changelog.yml
- type: StatusPage
  url: https://status.webcrawlerapi.com
- type: GitHubOrganization
  url: https://github.com/WebCrawlerAPI
- type: Twitter
  url: https://x.com/Webcrawlerapihq
- type: Pricing
  url: https://webcrawlerapi.com/docs/pricing
- type: SignUp
  url: https://dash.webcrawlerapi.com/sign-up
- type: Login
  url: https://dash.webcrawlerapi.com/sign-in
- type: TermsOfService
  url: https://webcrawlerapi.com/tos
- type: PrivacyPolicy
  url: https://webcrawlerapi.com/privacy
- type: RefundPolicy
  url: https://webcrawlerapi.com/refund
- type: Leadership
  url: https://webcrawlerapi.com/about
- type: Postman
  url: https://www.postman.com/webcrawlerapi/webcrawlerapi-public-workspace/collection/xz2fs5u/webcrawlerapi
- type: LLMsTxt
  url: llms/webcrawlerapi-com-llms.txt
- type: LLMsTxt
  name: llms.txt (provider-hosted)
  url: https://webcrawlerapi.com/llms.txt
- type: LLMsTxt
  name: docs llms.txt (provider-hosted)
  url: https://webcrawlerapi.com/docs/llms.txt
- type: WellKnown
  url: well-known/webcrawlerapi-com-well-known.yml
- type: APICatalog
  url: https://webcrawlerapi.com/.well-known/api-catalog
- type: AgentCard
  url: a2a/webcrawlerapi-com-a2a.yml
- type: MCPServer
  url: mcp/webcrawlerapi-com-mcp.yml
- type: ToolCrosswalk
  url: mcp/webcrawlerapi-com-tool-crosswalk.yml
- type: AgentSkill
  url: skills/_index.yml
- type: Packages
  url: packages/webcrawlerapi-com-packages.yml
- type: SDKs
  url: packages/webcrawlerapi-com-packages.yml
- type: CLI
  url: cli/webcrawlerapi-com-cli.yml
- type: Authentication
  url: authentication/webcrawlerapi-com-authentication.yml
- type: Conventions
  url: conventions/webcrawlerapi-com-conventions.yml
- type: ErrorCatalog
  url: errors/webcrawlerapi-com-problem-types.yml
- type: DataModel
  url: data-model/webcrawlerapi-com-data-model.yml
- type: Webhooks
  url: asyncapi/webcrawlerapi-com-webhooks.yml
- type: RateLimits
  url: rate-limits/webcrawlerapi-com-rate-limits.yml
- type: Plans
  url: plans/webcrawlerapi-com-plans-pricing.yml
- type: Lifecycle
  url: lifecycle/webcrawlerapi-com-lifecycle.yml
- type: Conformance
  url: conformance/webcrawlerapi-com-conformance.yml
- type: Overlay
  url: overlays/webcrawlerapi-com-openapi-overlay.yaml
- type: DomainSecurity
  url: security/webcrawlerapi-com-domain-security.yml
- type: Subprocessors
  url: https://webcrawlerapi.com/legal/subprocessor-list
- type: NoticeAndAction
  url: https://webcrawlerapi.com/tos
- type: UsageTerms
  url: terms/webcrawlerapi-com-terms-of-service.yml
- type: DataProcessing
  url: privacy/webcrawlerapi-com-privacy-policy.yml
- type: Eligibility
  url: eligibility/webcrawlerapi-com-eligibility.yml
- type: DataLicense
  url: data-license/webcrawlerapi-com-data-license.yml
x-enrichment:
  date: '2026-09-19'
  status: enriched
  artifacts_added: 30
  pass: local-v3

WebCrawlerAPI — frequently asked questions

Does WebCrawlerAPI have an API?

Yes. APIs.io lists 8 APIs from WebCrawlerAPI, including WebCrawlerAPI MCP Server, WebCrawlerAPI Agent Card and WebCrawlerAPI Agent API, and 5 more.

Is there an OpenAPI specification for the WebCrawlerAPI?

Yes. APIs.io indexes 6 OpenAPI specifications for WebCrawlerAPI, each linked for download from this page.

How do I authenticate with the WebCrawlerAPI?

WebCrawlerAPI uses bearer-token authentication (apiKey · 1 scheme). The details are profiled on APIs.io as WebCrawlerAPI Authentication.

How much does the WebCrawlerAPI cost?

WebCrawlerAPI publishes its prices; its Pay as you go plan is $0/month as of 2026-10-28. APIs.io lists 3 pricing plans for WebCrawlerAPI, with each plan's price, limits and inclusions under Pricing on this page.

Does WebCrawlerAPI have an MCP server?

Yes. APIs.io lists 2 MCP servers for WebCrawlerAPI: WebCrawlerAPI ships an official MCP server as an npm package (webcrawler-mcp) that a user runs locally over stdio, or self-hosts over HTTP with USE_HTTP=true. There is NO provider-hosted remote endpoi

Is the WebCrawlerAPI ready for AI agents?

WebCrawlerAPI has a Kin Score of 65.8 out of 100 (strong) and an Agent Readiness score of 43.0 (agent-ready), scored by API Evangelist on 2026-11-13.

Work with this as data

Every provider here is available over the APIs.io API and to AI agents over MCP.

MCP server

One button, every client — Claude, Cursor, VS Code and the rest.

https://apis.io/mcp

Tools for providers

9 MCP tools reach this
  • find_providersBrowse and filter every provider in the catalog.
  • get_provider_artifactsEvery artifact this provider publishes, grouped by type.
  • get_provider_operationsEvery operation across all of their OpenAPIs — one call instead of parsing every spec.
  • get_provider_toolsEvery MCP tool they ship, with the operation each wraps.
  • get_provider_evidenceHow each part of their score was established. Free — the basis for a claim should not sit behind it.
  • get_provider_ratingPRO — composite, band, trend and facet scores.
  • apis_io_searchSTART HERE — APIs, providers and tags for one query, each with its total.
  • resolveTurn a domain, URL or GitHub org into the provider it belongs to.
  • find_cohortsEvery scored population of providers in the catalog.
All 92 tools →

Call it yourself

curl for this page
This provider
curl "https://apis.io/api/v1/providers/webcrawlerapi-com"
All providers
curl "https://apis.io/api/v1/providers?limit=25"
Every operation they expose
curl "https://apis.io/api/v1/providers/webcrawlerapi-com/operations?limit=25"
How their score was established
curl "https://apis.io/api/v1/providers/webcrawlerapi-com/evidence"

Calls without X-API-Key need no key. Calls with it need a paid plan — get a key.

Get an API key

Free tier, no form to fill in. Signing in shares your email address with us — we store it to create your key and to recognise you if you sign in with another provider. See our Privacy Policy and Terms.

A second provider on the same verified email joins the account you already have.