Scalable Inference Serving
A collection of APIs, frameworks, and platforms for scalable machine learning model inference serving, deployment, and management. This includes the KServe Open Inference Protocol (the CNCF standard for model serving on Kubernetes), BentoML (developer packaging and serving), vLLM (high-throughput LLM inference), NVIDIA Triton Inference Server, and supporting observability and registry tools. KServe recently joined CNCF as an incubating project (November 2025).
Scalable Inference Serving publishes 9 API contracts indexed on the APIs.io network, including Health API, Inference API, Metadata API, and 6 more. Tagged areas include Artificial Intelligence, CNCF, Deployment, Inference, and Kubernetes.
The Scalable Inference Serving catalog on APIs.io includes 1 JSON-LD context and 2 Spectral governance rulesets.
Scalable Inference Serving’s developer surface includes authentication, getting-started guide, engineering blog, and 13 more developer resources.
What this lets a business do 1
Business capabilities this provider's published APIs can perform, derived from its own contracts. Browse all capabilities →
Kin Score
 Kin Score
How this is scored →
scored 2026-11-13 · rubric v0.28.0
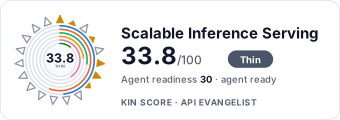 It updates itself when the score changes. Paste this where you link to your API docs:
<a href="https://apis.io/providers/scalable-inference-serving/"><img src="https://apis.io/badge/scalable-inference-serving/card.svg" alt="Scalable Inference Serving on APIs.io — Kin Score by API Evangelist"></a>Other styles, a README pill and a shields.io endpoint are on the badge page.
- MCP Server +12 pts — deployment.mode + probe verdict on the mcp/ manifest, not the pointer; an unprobed slug falls back to authorship Ask about this →
- Idempotency +9 pts — OpenAPI mutating operations declare an idempotency key — a header, a request-body property, or a named de-duplication token whose own description says so (verified); else common[].type matches /idempoten/i (documented) Ask about this →
- A2A Agent Card +8 pts — a2a/
-a2a.yml manifest, graded on conformance.grade against A2A 1.0.0 Ask about this → - Registration Without a Human +6 pts — a `registration_endpoint` in the served RFC 8414 / OIDC discovery document Ask about this →
- Delegated User Identity +6 pts — a served discovery document listing authorization_code in grant_types_supported (served), else an oauth2 authorizationCode flow or openIdConnect declared in an OpenAPI (documented) Ask about this →
- Typed Event Surface +6 pts — AsyncAPI document, OR webhooks/callbacks objects in the as-published OpenAPI, OR common[].type includes Webhooks Ask about this →
- Access Clarity scores 8.5 — up to +18.3 composite points Ask about this →
- Developer Ergonomics scores 40.5 — up to +11.9 composite points Ask about this →
- Contract Quality scores 55.4 — up to +11.2 composite points Ask about this →
Standards implemented 2
Standards this provider implements or carries. De facto ones are profiled and measured by the API Commons; formal ones come from the standards directory and are linked by the provider's own tags. The evidence column says how each claim was established — not that it was made.
APIs 9
Individual APIs this provider publishes, each with its own machine-readable definition.
BentoML REST API
BentoML is an open-source unified inference platform for deploying and scaling AI models. It auto-generates RESTful APIs from Python service definitions, provides built-in OpenA...
vLLM OpenAI-Compatible API
vLLM is a high-throughput and memory-efficient inference engine for LLMs, implementing PagedAttention for efficient KV cache management. vLLM exposes an OpenAI-compatible REST A...
NVIDIA Triton Inference Server HTTP API
NVIDIA Triton Inference Server is an open-source inference serving software that implements the KServe Open Inference Protocol (V2). Supports TensorRT, ONNX, TensorFlow, PyTorch...
MLflow Model Registry REST API
MLflow is an open source platform for managing the ML lifecycle, including experiment tracking, reproducibility, and deployment. The MLflow REST API manages experiments, runs, m...
Ray Serve REST API
Ray Serve is a scalable model serving library built on Ray, designed for building online inference APIs. Supports composable deployments, autoscaling, HTTP ingress, gRPC, WebSoc...
Scalable Inference Serving Health API
Server and model liveness and readiness probes
Scalable Inference Serving Inference API
Model inference request endpoints
Scalable Inference Serving Metadata API
Server and model metadata endpoints
Scalable Inference Serving Models API
Model management and metadata operations
Scroll for all 9
Open Collections 5
Open, tool-agnostic API collections (OpenAPI-derived and Bruno).
KServe Open Inference Protocol API
OPEN COLLECTIONKServe Open Inference Protocol Health API
OPEN COLLECTIONKServe Open Protocol Health Inference API
OPEN COLLECTIONKServe Open Inference Protocol Health Metadata API
OPEN COLLECTIONKServe Open Inference Protocol Health Models API
OPEN COLLECTIONScalable Inference Serving API pricing
Not yet checked against Scalable Inference Serving's own pricing page. Compiled by API Evangelist on 2026-05-05 from kserve.github.io/website/; confirm before you rely on a figure.
| Plan | Price |
|---|---|
| Contact Sales enterprise | — |
Plan details, limits and sources →
Rate limits
- Contracted limits: negotiated under commercial / partner agreement; not publicly published varies
Compiled by API Evangelist, not yet checked against Scalable Inference Serving's documentation. Rate-limit details →
Pricing Plans 1
Published pricing tiers and plan structures.
Rate Limits 1
Documented rate limits and quota policies.
Scalable Inference Serving Rate Limits
RATE LIMITSFinOps 1
Cost, billing, and metering signals for API financial operations.
Semantic Vocabularies 1
JSON-LD contexts and semantic vocabularies used across these APIs.
Spectral Rules 2
Spectral governance rulesets for linting and validating these APIs. Counts are the severity each rule declares, not results of running them.
JSON Schema 15
Standalone JSON Schema definitions for this provider's data models.
Inference Request
JSON SCHEMAModel Metadata
JSON SCHEMAErrorResponse
JSON SCHEMAInferenceRequest
JSON SCHEMAInferenceResponse
JSON SCHEMAModelMetadataResponse
JSON SCHEMAModelReadyResponse
JSON SCHEMARequestInput
JSON SCHEMARequestOutput
JSON SCHEMAResponseOutput
JSON SCHEMAServerLiveResponse
JSON SCHEMAServerMetadataResponse
JSON SCHEMAServerReadyResponse
JSON SCHEMATensorDatatype
JSON SCHEMATensorMetadata
JSON SCHEMAScroll for all 15
JSON Structure 2
JSON Structure definitions describing this provider's data shapes.
Kserve Inference Request Structure
JSON STRUCTUREScalable Inference Serving Structure
JSON STRUCTUREExamples 9
Example request and response payloads for these APIs.
Kserve Run Inference Example
EXAMPLEScroll for all 9
Agentic Access (API Evangelist recommendations) 1
Recommended x-agentic-access execution contracts for AI agents.
Resources
Get Started 1
Portal, sign-up, and the first successful call
Documentation 3
Reference material describing how the API behaves
Agent Surfaces 1
MCP servers, agent skills, and machine-readable catalogs
Design & Contract 3
Pagination, idempotency, versioning, errors, and events
Build 1
SDKs, sample code, and the tooling you integrate with
Access & Security 1
Authentication, authorization, and security posture
Operate 1
Status, limits, changes, and where to get help
Commercial 2
Pricing, plans, and the legal terms of use
Company 1
The organization behind the API
Other 2
Properties that don't map to a standard resource type
Source (apis.yml)
Scalable Inference Serving API — frequently asked questions
Does Scalable Inference Serving have an API?
Yes. APIs.io lists 9 APIs from Scalable Inference Serving, including BentoML REST API, vLLM OpenAI-Compatible API and NVIDIA Triton Inference Server HTTP API, and 6 more.
Is there an OpenAPI specification for the Scalable Inference Serving API?
Yes. APIs.io indexes 4 OpenAPI specifications for Scalable Inference Serving, each linked for download from this page.
How do I authenticate with the Scalable Inference Serving API?
Scalable Inference Serving uses bearer-token authentication.
How much does the Scalable Inference Serving API cost?
APIs.io lists 1 pricing plan for Scalable Inference Serving, with each plan's price, limits and inclusions under Pricing on this page.
Is the Scalable Inference Serving API ready for AI agents?
Scalable Inference Serving has a Kin Score of 33.4 out of 100 (thin) and an Agent Readiness score of 30.2 (agent-ready), scored by API Evangelist on 2026-11-13.
Work with this as data
Every provider here is available over the APIs.io API and to AI agents over MCP.