Confident AI
Confident AI is the company behind DeepEval, the widely adopted open-source LLM evaluation framework, and the Confident AI cloud platform that layers observability, dataset management, regression testing, and red teaming on top of the local framework. DeepEval treats LLM evaluation as unit testing with research-backed metrics such as GEval, AnswerRelevancy, and Faithfulness, while DeepTeam provides an open-source red teaming framework. The hosted platform is SOC 2 Type II, HIPAA, and GDPR compliant with self-hosting available for regulated customers.
Confident AI is listed with 3 APIs on the APIs.io network. Tagged areas include LLM Evaluation, Open Source, Observability, Red Teaming, and Guardrails.
Confident AI’s developer surface includes documentation, engineering blog, pricing, and 18 more developer resources.
Kin Score
 Kin Score
How this is scored →
scored 2026-11-06 · rubric v0.27.0
 It updates itself when the score changes. Paste this where you link to your API docs:
<a href="https://apis.io/providers/confident-ai/"><img src="https://apis.io/badge/confident-ai/card.svg" alt="Confident AI on APIs.io — Kin Score by API Evangelist"></a>Other styles, a README pill and a shields.io endpoint are on the badge page.
- Machine-Readable Contract +18 pts — api_specs includes an OpenAPI document
- Agentic Access Contract +10 pts — agentic_access artifact present (x-agentic-access), graded by author
- Machine-Readable Auth +10 pts — a served openid-configuration/oauth-authorization-server carrying `issuer` (served), else the securitySchemes class in the provider OpenAPIs — bound (mutualTLS, DPoP, Signature) > negotiable (oauth2 authorizationCode/clientCredentials, openIdConnect) > bearer (http bearer, apiKey)
- Idempotency +9 pts — OpenAPI mutating operations declare an idempotency key — a header, a request-body property, or a named de-duplication token whose own description says so (verified); else common[].type matches /idempoten/i (documented)
- Stable Error Semantics +8 pts — OpenAPI $refs a shared error schema across 4xx/5xx responses (verified), else common[].type includes ErrorCatalog / ErrorCodes / DeclineCodes
- A2A Agent Card +8 pts — a2a/
-a2a.yml manifest, graded on conformance.grade against A2A 1.0.0
- Contract Quality scores 0.0 — up to +25.0 composite points
- Access Clarity scores 22.4 — up to +15.5 composite points
- Developer Ergonomics scores 31.0 — up to +13.8 composite points
Standards implemented 2
Standards this provider implements or carries. De facto ones are profiled and measured by the API Commons; formal ones come from the standards directory and are linked by the provider's own tags. The evidence column says how each claim was established — not that it was made.
APIs 3
Individual APIs this provider publishes, each with its own machine-readable definition.
DeepEval
DeepEval is an open-source Python framework for evaluating LLM applications as unit tests. It ships with research-backed metrics including GEval, AnswerRelevancyMetric, Faithful...
Confident AI Platform
Confident AI is the hosted platform that complements DeepEval with observability, centralized reporting, regression testing, prompt versioning, dataset management, trace ingesti...
DeepTeam
DeepTeam is Confident AI's open-source red teaming framework for stress-testing LLM applications against adversarial attacks including prompt injection, jailbreaks, PII leakage,...
MCP Servers 1
Model Context Protocol servers that expose these APIs to AI agents.
Confident AI API pricing
Not yet checked against Confident AI's own pricing page. Compiled by API Evangelist on 2026-05-22; confirm before you rely on a figure. A free plan or tier is listed.
| Plan | Price |
|---|---|
| Free freemium | Free |
Plan details, limits and sources →
Rate limits
- Free Tier Default: 10 requests per minute
- Pro Tier Default: 120 requests per minute
Compiled by API Evangelist, not yet checked against Confident AI's documentation. Rate-limit details →
Pricing Plans 1
Published pricing tiers and plan structures.
Rate Limits 1
Documented rate limits and quota policies.
Confident Ai Rate Limits
RATE LIMITSFinOps 1
Cost, billing, and metering signals for API financial operations.
Confident Ai Finops
FINOPSFeatures 10
Notable capabilities this provider offers.
DeepEval Framework
Open-source Python framework for evaluating LLM apps as unit tests with research-backed metrics.
GEval Metric
LLM-as-a-judge metric for custom evaluation criteria configurable by natural language rubric.
LLM Tracing
Component-level tracing of LLM calls, retrieval steps, and tool usage for agents.
Observability
Hosted dashboards for traces, latencies, costs, and metric scores across production runs.
Regression Testing
Detect quality regressions against historical baselines as part of CI.
Prompt Versioning
Centralized prompt registry with version history and rollout.
Dataset Management
Manage evaluation datasets, synthetic data generation, and human annotations.
Red Teaming
DeepTeam framework for adversarial testing against LLM applications.
Self-Hosting
Self-hosted deployment available for regulated customers.
Compliance
SOC 2 Type II, HIPAA, and GDPR compliant cloud platform.
Scroll for all 10
Security Posture 1
Authentication, domain security, vulnerability disclosure, and trust-center signals.
Use Cases 5
What developers build with this provider.
Unit Testing LLM Apps
Treat LLM evaluations as pytest-style unit tests inside developer workflows and CI.
RAG Evaluation
Score retrieval, faithfulness, and answer quality in RAG pipelines.
Agent Evaluation
Trace and evaluate multi-step agents with component-level metrics.
Production Observability
Stream production traces to Confident AI for monitoring and alerting.
Red Teaming
Run adversarial test suites with DeepTeam to find security and safety failures.
Integrations 11
Pre-built integrations with other platforms and tools.
OpenAI
Evaluate OpenAI Chat Completions and Assistants outputs.
Anthropic
Evaluate Anthropic Claude outputs.
LangChain
Native integration for evaluating LangChain chains and agents.
LangGraph
Trace and evaluate LangGraph stateful agents.
LlamaIndex
Evaluate LlamaIndex RAG pipelines.
CrewAI
Trace and evaluate CrewAI multi-agent crews.
Pydantic AI
Integrate evaluators with Pydantic AI agents.
OpenTelemetry
Ingest OTel traces for evaluation and observability.
Ollama
Use local Ollama models as evaluators or as systems under test.
Azure OpenAI
Evaluate Azure-hosted OpenAI deployments.
Gemini
Evaluate Google Gemini model outputs.
Scroll for all 11
Resources
Get Started 1
Portal, sign-up, and the first successful call
Documentation 4
Reference material describing how the API behaves
Build 3
SDKs, sample code, and the tooling you integrate with
Access & Security 2
Authentication, authorization, and security posture
Operate 4
Status, limits, changes, and where to get help
Commercial 4
Pricing, plans, and the legal terms of use
Company 3
The organization behind the API
Source (apis.yml)
Confident AI API — frequently asked questions
Does Confident AI have an API?
Yes. APIs.io lists 3 APIs from Confident AI, including DeepEval, Confident AI Platform and DeepTeam.
How much does the Confident AI API cost?
APIs.io lists 1 pricing plan for Confident AI, with each plan's price, limits and inclusions under Pricing on this page.
Does Confident AI have an MCP server?
Yes. APIs.io lists 1 MCP server for Confident AI: Remote MCP server at mcp.confident-ai.com over HTTP.
Is the Confident AI API ready for AI agents?
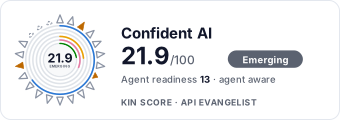
Confident AI has a Kin Score of 21.9 out of 100 (emerging) and an Agent Readiness score of 12.9 (agent-aware), scored by API Evangelist on 2026-11-06.
Work with this as data
Every provider here is available over the APIs.io API and to AI agents over MCP.